


Best Hybrid Proxies for Web Scraping
Scrape Amazon without bans, CAPTCHAs or wasted retries
- Clean & undetectable IPs
- 99%+ Success Rate
- 120M+ IPs across 195 countries
Why Most Web Scraping Setups Fail
Most scraping failures aren’t caused by code, they’re caused by IP reputation, detection patterns and unstable sessions.
IP Reputation Blacklisting
Datacenter and low-quality residential IPs are pre-flagged. Entire ASN ranges are blocked before your request is even processed.
Detection Beyond IPs
Modern sites analyze TLS fingerprints, request headers, and session behavior. Automation patterns trigger blocks even with rotating IPs.
CAPTCHA & Retry Traps
Blocked requests lead to endless CAPTCHAs and retries, inflating costs while returning unusable data.
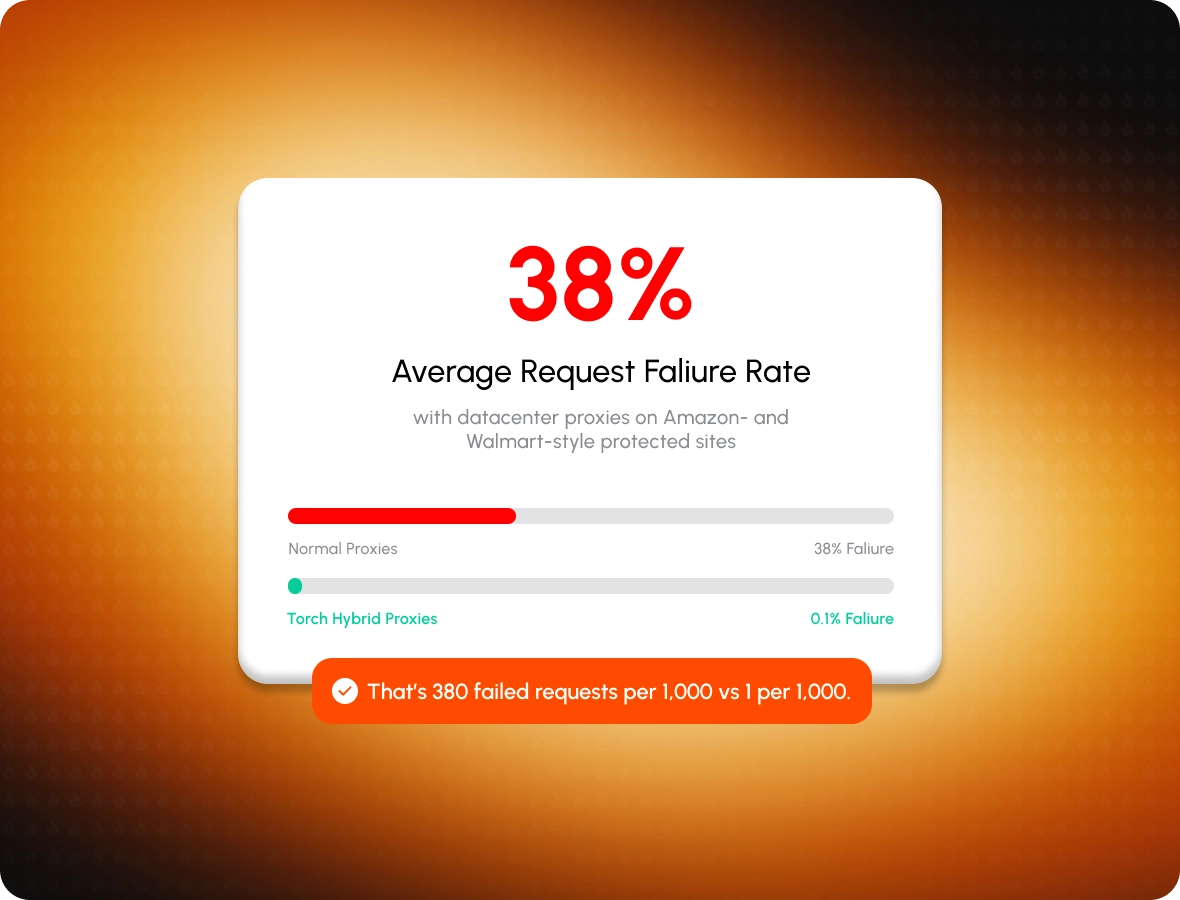
Why Detection Ruins
Scraping Accuracy
Incomplete or Fake Data
Blocked sessions return CAPTCHA pages, redirects or placeholders instead of real content.
Runaway Infrastructure Costs
Retries, proxy rotation and CAPTCHA solving multiply costs without improving results.
Missed Coverage at Scale
Unstable proxies make it impossible to scrape consistently across regions, categories or time windows.
One Proxy Built for Reliable Web Scraping
A single proxy solution designed for teams that scrape at scale and can’t afford blocks, retries, or wasted spend.
Hybrid Proxies for Web Scraping
Built for modern scraping environments where detection resistance, consistency and cost control matter more than raw bandwidth.
- Fewer blocks, fewer retries, cleaner data
- Stable sessions for complex scraping workflows
- One proxy type that works across all targets
- Better ROI at high request volumes
Why Hybrid Proxies Work for Web Scraping
Hybrid proxies combine real residential identity with high-performance infrastructure so your scraping runs longer,
costs less and fails less often.
Most blocks happen before scraping even starts. Hybrid proxies use real ISP backed identities that websites trust.
- ISP sourced IPs that look like real users
- No datacenter fingerprints that trigger instant blocks
- 99% success rate even on heavily protected sites
What this means for you?
Your requests go through instead of getting silently blocked.
Retries, bans and failed requests are what make scraping expensive, not bandwidth.
- From $5/GB with far fewer retries
- Up to 60% cheaper than traditional residential proxies
- Non expiring traffic means nothing goes to waste
What this means for you?
You spend less money to get the same or better results.
Managing multiple proxy types adds complexity and failure points. Hybrid proxies handle everything with one setup.
- Works on both easy sites and strict, protected platforms
- No switching between datacenter and residential pools
- Residential trust with datacenter-level efficiency
What this means for you?
Simpler infrastructure and fewer things to maintain.
CAPTCHAs are triggered by suspicious IP reputation and automation signals. Hybrid proxies reduce both.
- Clean ISP reputation lowers CAPTCHA frequency
- Real residential authentication signals
- No need for CAPTCHA-solving services
What this means for you?
More uninterrupted scraping and cleaner data.
The Right Proxies for Price Monitoring
Choose the right proxy based on whether your target sites use advanced anti-bot protection and how large your monitoring scale is.
Hybrid Proxies
Built for limited drops, queues and high-pressure checkouts
$5/GB
- 99% success rate on protected and high-friction sites
- ISP sourced residential IPs that pass anti-bot checks
- Stable sessions for consistent, large scale scraping
- Easy API integration for rapid deployment
- Best price-performance at scale
What this means for you?
- More successful requests per GB
- Fewer retries, blocks and CAPTCHA loops
- Lower cost per usable dataset
Best for
See how we compare with others
Proof why we are the best option for your use case
 |  |  |  |  | |
|---|---|---|---|---|---|
Price | $8 per GB | $8 per GB | $5 per GB | $4 per GB | $4 per GB |
Pool Size | 150M+ IPs | 175M+ IPs | 120M IPs | 29.5M+ IPs | 30M+ IPs |
Countries | 195 Countries | 195+ Countries | 195+ Countries | 170+ Countries | 195+ Countries |
Minimum Purchase | Pay as you go (No Minimum) | Pay as you go (5 GB Min) | Pay as you go (No Minimum) | Pay as you go (No Minimum) | Pay as you go (9 GB Min) |
Free Trial |  | | |  | |
getting blocked
protected and open websites.
- No Credit Card Required
- Set up in minutes
- Works in 195+ countries
FAQ
Frequently asked questions
A proxy in web scraping is a server that sits between your scraper and the target website , forwarding your requests using its own IP address instead of yours. The target site sees the proxy's IP, not your real one. When you rotate through a large pool of proxies, every request appears to come from a different individual user across different locations.
Rotating Residential Proxies — The most reliable choice for highly protected targets: Amazon, Google, LinkedIn, Instagram, Booking.com, Cloudflare-protected sites, and DataDome-protected platforms. Real ISP-assigned IPs that blend into genuine user traffic. Higher cost per GB but dramatically lower ban rates on Tier-1 targets. Best used with session-based rotation (sticky IPs per scrape session).
Fast
Rotating Datacenter Proxies — Fastest and most cost-effective for lower-protection targets: news sites, Wikipedia, public government databases, job boards like Indeed, and unprotected e-commerce catalogues. Ideal for high-volume scraping where speed matters more than IP legitimacy. Easily detected by Akamai, Cloudflare, and Distil Networks.
Hybrid
ISP (Static Residential) Proxies — Best for sustained, long-running crawls on mid-tier targets: Yelp, Tripadvisor, Zillow, Rightmove, and mid-size e-commerce platforms. Datacenter speed with residential IP registration , keeps sessions stable over hours without the rotation overhead of residential proxies.
The right number of proxies isn't a fixed figure, it depends on your request volume, how aggressively the target site rate-limits, and your rotation strategy. The key metric to manage is requests per IP per hour , not total proxy count. Keeping this below the site's detection threshold is what prevents bans
Strict
Google, Amazon, LinkedIn — Keep below 5–10 requests per IP per hour. These platforms run aggressive bot detection and will ban IPs at low thresholds. Use large residential pools with session rotation.
Moderate
E-commerce sites, booking platforms, job boards — Keep below 20–50 requests per IP per hour. Mid-tier rate limiting , residential or ISP proxies with 10–30 minute sticky sessions work well.
Lenient
News sites, public directories, government databases — Keep below 100–200 requests per IP per hour. Low detection risk. Datacenter proxies are sufficient and cost-effective at this tier.
Proxies win for web scraping , without exception at any meaningful scale. A VPN provides a single IP address shared across all your traffic. For scraping, where you need to distribute thousands of requests across thousands of different IPs to avoid detection, a VPN achieves nothing that a proxy doesn't also do while adding encryption overhead, speed penalties, and a single point of failure.